Scaling Innovation Across Borders: A Practical Playbook
A field manual for scaling innovation across borders with local discovery rights, shared platforms, written decision packets and a 90-day operating cadence.
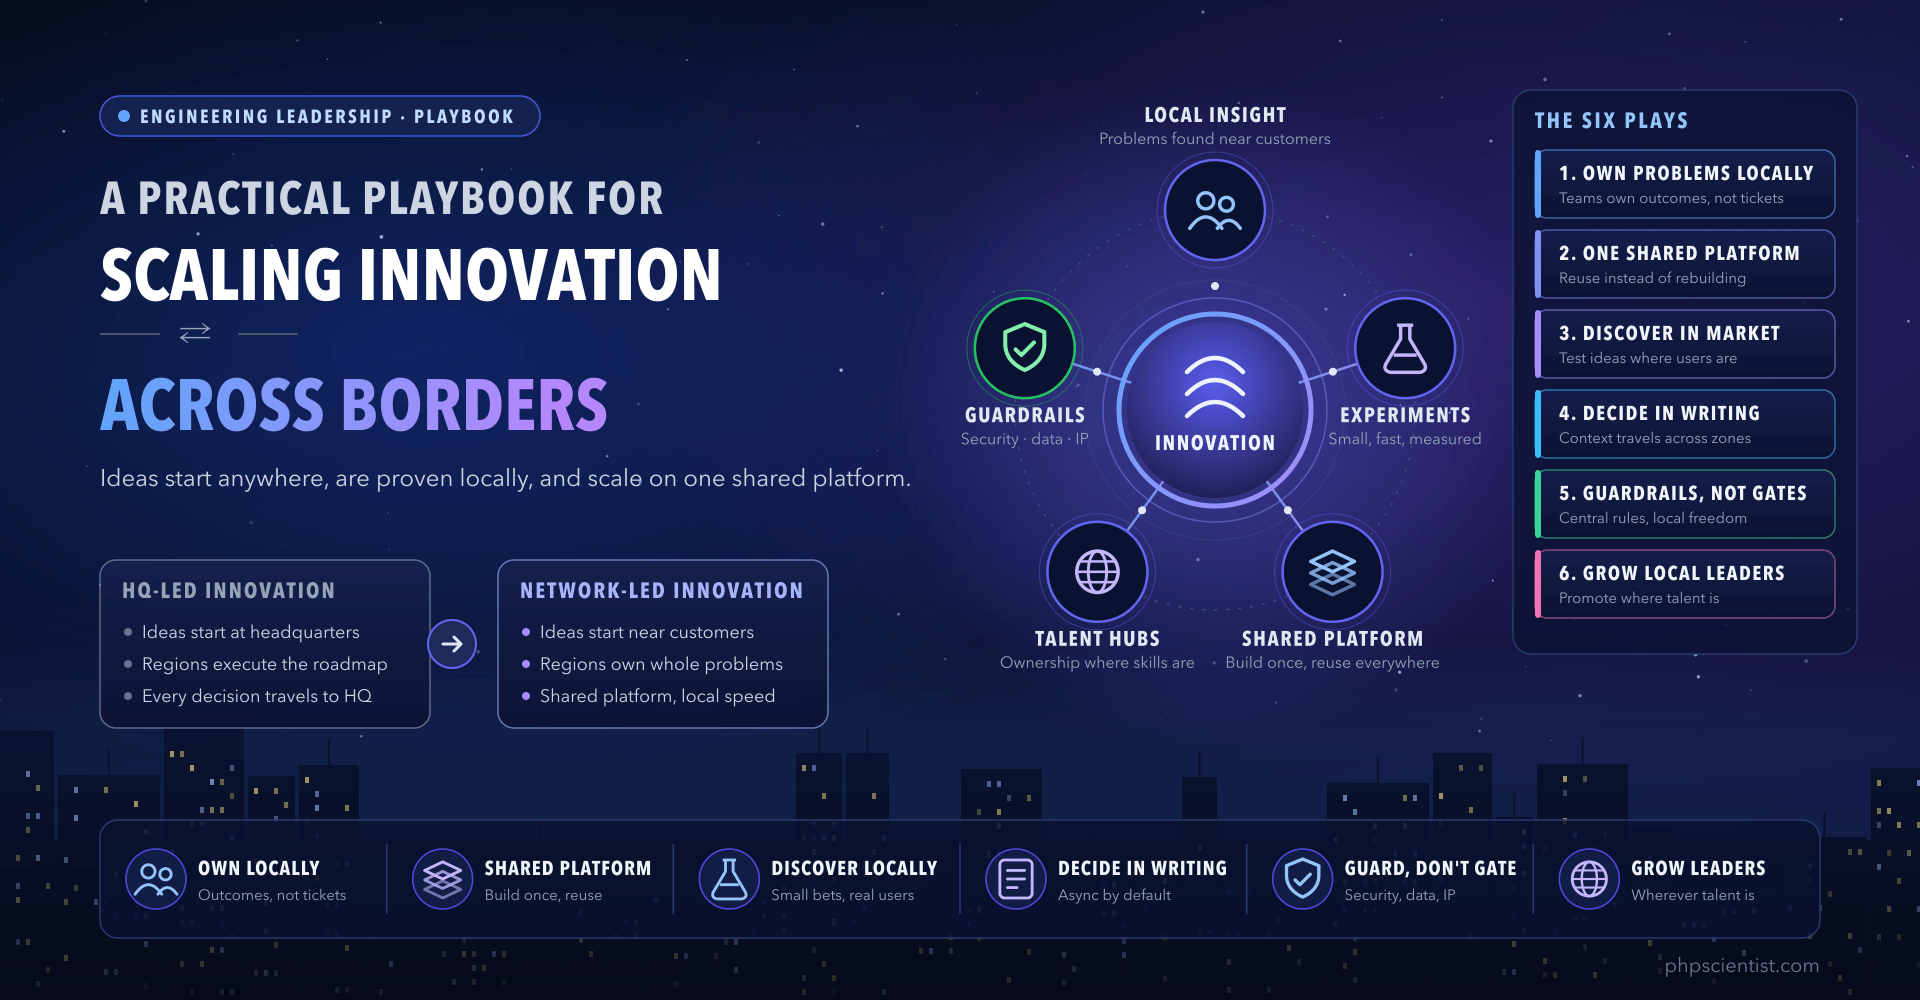
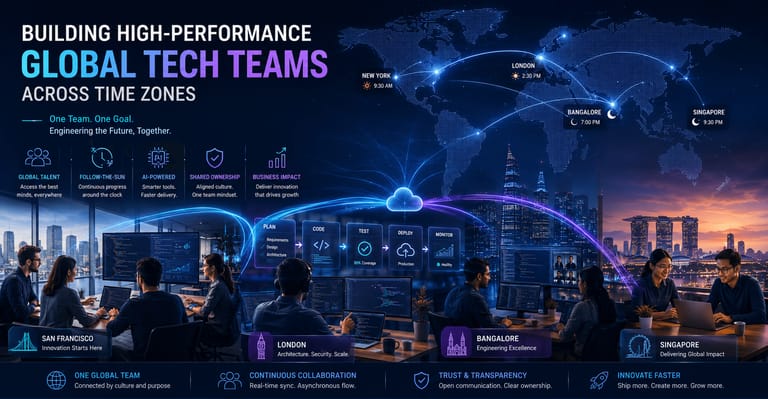
Scaling innovation across borders is not a travel problem, a time-zone problem or a hiring problem. It is an operating-system problem. Ideas need a way to start close to customers, prove value locally and then move across the company without being rewritten by every region.
The cross-border innovation map
Most global innovation programmes fail in one of two ways. Headquarters centralises everything and misses local nuance, or regions innovate independently and create a portfolio of disconnected tools. The practical model is a network: local discovery, shared platforms, explicit guardrails and fast evidence loops.
- 4 zones
- Discover locally, prove locally, scale globally, govern centrally
- 6 plays
- Operating moves that stop global innovation becoming theatre
- 90 days
- Enough time to prove whether the model works in two regions
- 1 platform
- Shared engineering spine that lets regional ideas travel
Border friction diagnostic
Before changing structure, diagnose the friction. Cross-border innovation usually slows down because teams lack shared context, shared platforms or shared decision rights. The symptom looks cultural, but the root cause is often operational.
Customer distance
- HQ owns the roadmap but regional teams hear the actual objections.
- Fix by giving local teams discovery budgets and customer-access rights.
Platform fragmentation
- Every market builds a different stack for the same product capability.
- Fix by defining reusable APIs, design systems and data contracts.
Time-zone delay
- Decisions wait for meetings instead of moving through written context.
- Fix by making decision records the default, not a follow-up.
Unclear authority
- Regional teams can suggest ideas but cannot commit people or funding.
- Fix with decision rights by stage: discover, test, scale and retire.
Late governance
- Security, data and legal reviews arrive after a pilot already has users.
- Fix with guardrails that teams can self-check before they build.
Weak signal sharing
- A win in one region becomes a story, not a reusable asset.
- Fix by packaging evidence, playbooks and reusable components together.
The six plays
Play 1: Create local discovery rights
Give regional teams permission to discover problems before asking for global alignment. That means customer interviews, prototype budgets and access to local commercial data. The guardrail is simple: they can explore many problems, but they must describe the evidence before asking the company to scale one.
Play 2: Build on one engineering spine
Innovation does not scale if every region solves the same plumbing differently. Standardise the unglamorous foundations: identity, analytics, deployment, observability, core APIs, data contracts and design primitives. Freedom increases when the shared platform removes repetitive setup work.
Play 3: Use written decision packets
A decision packet is a one-page artefact that explains the customer problem, evidence, expected value, risk, required platform work and decision needed. It travels better than a meeting. It also makes trade-offs visible to teams who are asleep when the discussion happens.
- Customer problem
- Experiment evidence
- Business upside
- Operational risk
- Platform dependency
- Decision requested
Play 4: Separate guardrails from approvals
Guardrails are published rules teams can use without asking permission. Approvals are moments where risk or investment crosses a threshold. Mature organisations reduce approval volume by improving guardrail clarity.
Play 5: Rotate talent without moving ownership
Short rotations help teams share context, but they should not remove local ownership. Send platform engineers into regions to accelerate reuse. Bring regional product leaders into global planning to represent customer nuance. Then send them back with authority intact.
Play 6: Package wins as assets
A successful regional experiment should ship with more than a demo. Package the component, decision packet, customer evidence, risk notes, rollout checklist and support model. Scaling starts when another region can reuse the work without needing the original team in every meeting.
Decision rights by stage
Local teams decide
- Which customer problems deserve discovery.
- Which experiments fit the local market context.
- Which adoption barriers need product or process changes.
- When a local idea has enough evidence to request scale funding.
Central teams decide
- Security, privacy, data residency and IP guardrails.
- Shared platform architecture and integration standards.
- Investment thresholds for multi-region scaling.
- When duplicate regional solutions should converge.
90-day operating cadence
Do not start by reorganising. Start with two regions, one shared platform team and one executive sponsor. The experiment is to prove that an idea can move from local evidence to reusable company asset without being trapped in meetings.
Days 1–15: choose the route
Pick two regions with different customer realities. Select one workflow or product area where both regions feel pain but express it differently.
Days 16–35: collect local evidence
Run customer interviews, support-ticket analysis and lightweight prototypes. Capture findings in written decision packets, not slide theatre.
Days 36–60: build the reusable spine
Let one region lead the experiment while platform engineers make the reusable pieces explicit: APIs, events, data definitions, design patterns and rollout notes.
Days 61–75: transfer to the second region
Ask the second region to adopt or adapt the asset without the first region doing all the translation. Track what breaks.
Days 76–90: scale, stop or split
If the idea travels with light adaptation, scale it. If it only works locally, keep it local. If both regions need different versions, split deliberately instead of pretending one size fits all.
Metrics that show the network is working
Innovation metrics should reveal movement across the network, not only activity inside one hub. A busy hub can still be a dead end if none of its work travels.
- Idea travel rate
- Share of shipped ideas adopted by at least one other region
- Reuse ratio
- How much of a regional build becomes shared platform asset
- Decision lead time
- Days from evidence packet to scale, stop or local-only decision
- Local evidence mix
- Percentage of roadmap bets backed by customer evidence outside HQ
The practical rule
The best global innovation systems are not borderless. They are border-aware. They use local differences as signal, shared platforms as leverage and written decisions as the bridge between both.
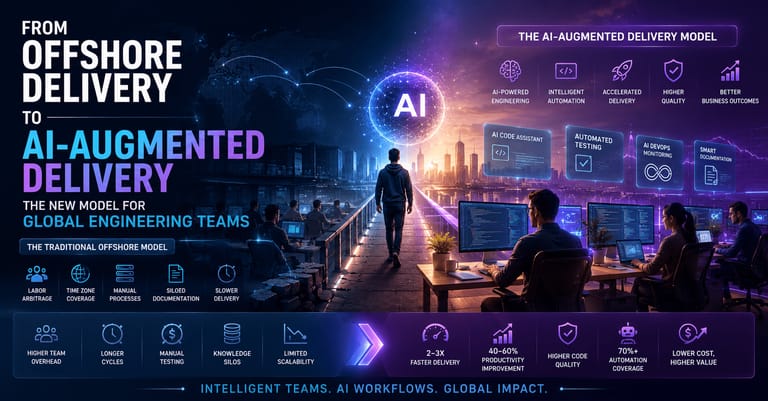
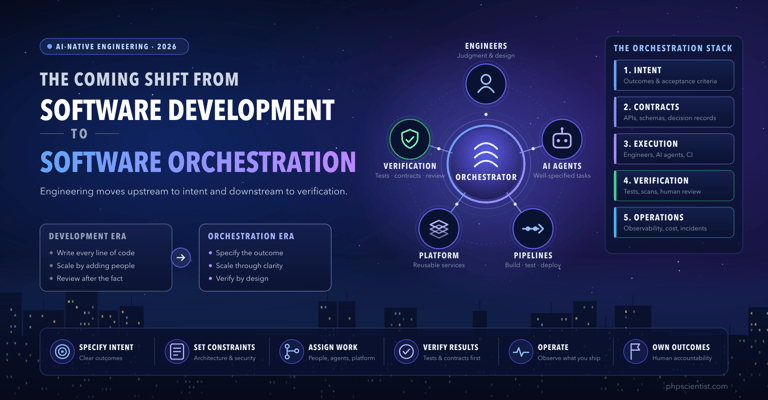
Related reading: how AI is reshaping the platform layer in The Coming Shift From Software Development to Software Orchestration, and how delivery models are evolving in From Offshore Delivery to AI-Augmented Delivery.
Frequently asked questions
How do companies scale innovation across borders?
Companies scale innovation across borders by letting regions discover customer problems locally while using shared platforms, written decision packets and central guardrails to turn proven ideas into reusable assets.
What should be centralised in global innovation?
Central teams should own security, privacy, platform architecture, data standards, IP guardrails and investment thresholds, while local teams own discovery and market-specific experimentation.
How do you measure distributed innovation?
Measure idea travel rate, reuse ratio, decision lead time and the share of roadmap bets backed by evidence from outside headquarters.