What is a vector database?
Short answer
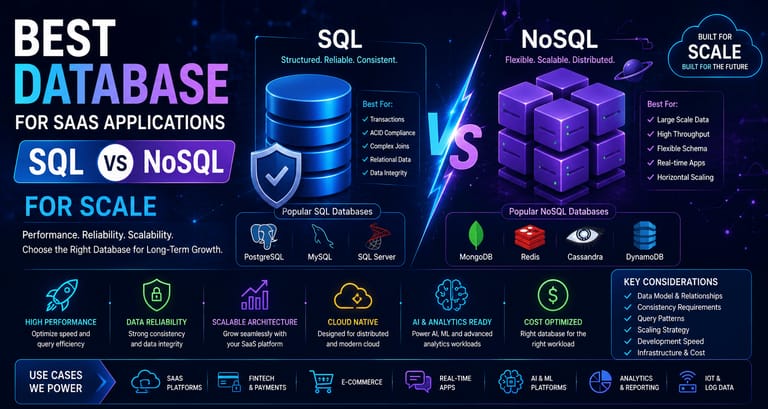
A vector database stores embeddings (numeric representations of meaning) and finds the ones most similar to a query vector quickly, using approximate nearest-neighbour indexes. It is the retrieval layer behind semantic search and RAG. Examples include Pinecone, Weaviate, Qdrant and Milvus; PostgreSQL with the pgvector extension does the same job inside a regular database.
What it does
Comparing a query against millions of vectors one by one is too slow. Vector databases build indexes, commonly HNSW (graph-based) or IVF (cluster-based), that return the nearest matches in milliseconds, trading a tiny amount of accuracy for speed. Most also filter on metadata, such as “only this customer’s documents”, and some combine vector and keyword search.
Do you need a separate one?
Often not. If your app already runs on PostgreSQL, the pgvector extension adds a vector column type and HNSW indexes, keeps embeddings next to the data they describe, and lets you use transactions, joins and row-level permissions you already have. Consider a dedicated vector database when you reach tens of millions of vectors, need very high query rates, or want managed scaling.
Questions to ask before choosing
- How many vectors, and how fast will that grow?
- Do results need filtering by tenant or permissions?
- Can it run where your data must stay (region, compliance)?
- What does it cost to re-index when you switch embedding models?