What is RAG (retrieval-augmented generation)?
Short answer
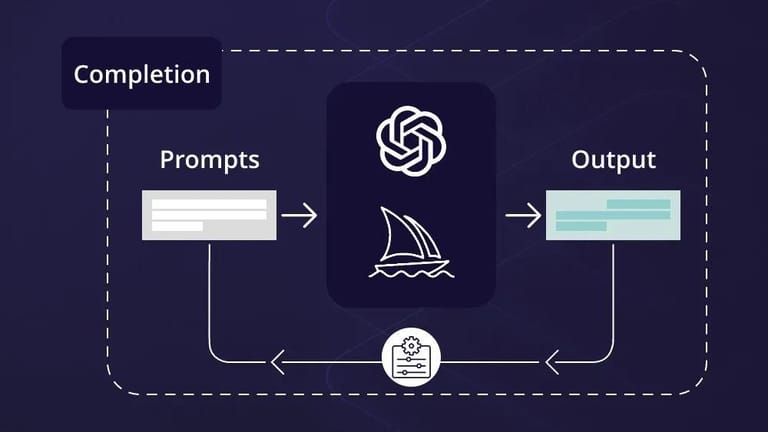
RAG (retrieval-augmented generation) is a technique where an AI application first retrieves relevant passages from your own documents or data, then gives them to a large language model together with the question. The model answers from that supplied context, which makes answers more current, more specific and easier to check against sources.
How RAG works
- Prepare: split documents into chunks of a few hundred words and turn each chunk into an embedding, stored in a vector database or a column such as PostgreSQL’s pgvector.
- Retrieve: when a question arrives, embed it the same way and find the most similar chunks (often combined with keyword search).
- Generate: put the best chunks into the prompt with an instruction like “answer only from these sources and cite them”, and send it to the model.
An example
A support assistant for a SaaS product retrieves the three most relevant help-centre articles for “How do I export invoices?”, and the model writes a step-by-step answer with links to those articles. When the documentation changes, you re-index it; nothing needs retraining.
RAG or fine-tuning?
Use RAG when answers depend on facts that change or must be traceable to a source. Use fine-tuning to change how a model writes or behaves, not to teach it facts.
Common mistakes
- Chunks that are too large or cut sentences mid-thought, so the right passage is never retrieved.
- No evaluation set: keep 20–50 real questions with known answers and test every change against them.
- Trusting retrieved text blindly: documents can contain instructions that hijack the model (prompt injection).
Frequently asked questions
Does RAG stop hallucinations?
It reduces them by giving the model the facts it needs, but does not eliminate them. Asking for citations, saying “I don’t know” when sources are missing, and testing with an evaluation set all help.
Can I build RAG in PHP?
Yes. Store embeddings in PostgreSQL with pgvector (or a hosted vector database), call an embeddings API and an LLM API over HTTP from Laravel or Symfony, and run indexing in queued jobs.